
AI Topic Research Agent: Find Technical Blog Ideas with Google, Reddit, and GitHub
"The Google Search Analytics API supports query and page dimensions, a rowLimit from 1 to 25,000, and startRow pagination, while explicitly stating that it does not guarantee every data row."
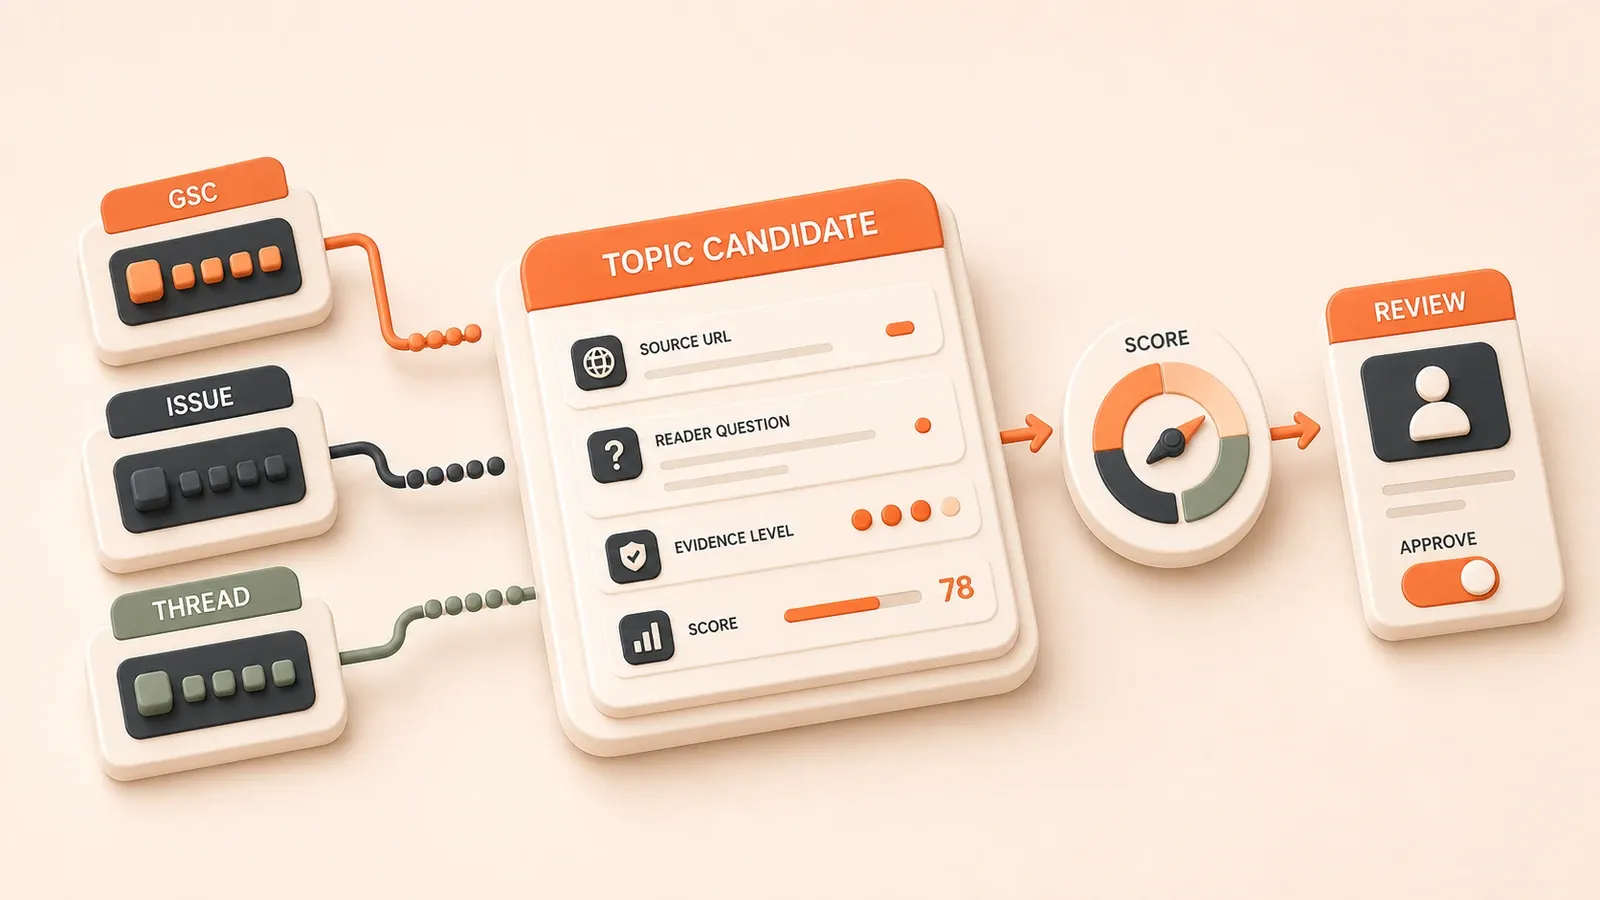
A candidate-topic table usually starts with three columns: source_url stores the origin, reader_question captures how readers phrase the problem, and evidence_level records confidence in the evidence. A forum-sourced prompt belongs in the second column, not in fact_claim; technical facts still require official documentation or a reproduced error.
A topic research agent is not a trend-chasing bot. It turns actual Google Search Console queries and technical friction from GitHub issues into auditable candidate cards. Separate forum inputs supply the language readers use for their problems. Scoring, deduplication, and risk filters decide what reaches the content backlog. The process is repeatable and reviewable instead of depending on inspiration.
Design the input layer for a topic research agent
Google first-party data: Performance report and API boundaries
The first input layer should come from your own site’s search data rather than a third-party trend score. Google Search Console’s Performance report exposes four core metrics and six dimensions.
Performance report dimensions
| Dimension type | Field | Purpose |
|---|---|---|
| Query | queries | Shows what readers actually type and surfaces high-impression, low-click candidates |
| Page | pages | Reveals which pages already receive traffic and prevents duplicate coverage |
| Country or region | countries | Captures regional differences when a topic applies only to certain markets |
| Device | devices | Separates mobile and desktop behavior, which can affect format and depth |
| Search appearance | search appearance | Identifies rich-result types and possible structured-data gaps |
| Date | dates | Defines sampling and comparison windows |
The four metrics are clicks, impressions, CTR, and average position. impressions is especially useful for topic discovery: when a query earns impressions but no clicks, readers are looking for something your site may not cover clearly enough.
Search Console API query design and limits
Programmatic access uses the searchAnalytics.query method. According to Google’s documentation as of July 2026, the method requires OAuth authorization, accepts a rowLimit from 1 to 25,000, and supports dimensions such as query or page, filters such as country or device, and aggregationType.
Two constraints matter. First, the API does not guarantee every data row; Search Console’s internal limits favor top rows. Second, requests for recent data can include metadata that identifies dates or hours still being processed. The agent should paginate, cache results, and retain an incomplete-data flag rather than treating an export as an exhaustive dataset.
Custom Search JSON API migration warning
Google Custom Search JSON API was once a common way to run web searches programmatically, but its official page now says it is closed to new customers and that existing customers must migrate by January 1, 2027. A new system should use a supported search product or a general search gateway instead of depending on this API.
If an existing project still uses Custom Search JSON API, plan the migration early and keep the search provider replaceable in configuration.
GitHub input: Search API boundaries and issue query templates
GitHub is a strong source of technical topic ideas. Issue titles often describe an actual error or product constraint, while release notes and discussions can reveal version changes and requests for better practices. The GitHub Search API also has firm limits.
GitHub Search API limits and rate limits
| Type | Rate limit | Notes |
|---|---|---|
| authenticated search, excluding code | 30 requests/min | Requires a token and suits continuous collection |
| unauthenticated search | 10 requests/min | Public access suitable only for low-frequency tests |
| code search | 10 requests/min | Requires authentication for source-code queries |
Each search provides at most 1,000 results, and pagination cannot expose anything beyond that limit. A query can also time out; the JSON response then sets incomplete_results: true, which means the returned set may be incomplete.
Issue query templates and article-type mapping
GitHub search supports composable qualifiers:

is:issue state:open label:bug in:title error repo:user/repo-name
is:issue state:closed reason:"completed" in:body "how to" repo:user/repo-name
is:pr state:open label:"enhancement" in:title repo:user/repo-name
Common qualifiers include is:issue and is:pr for the resource type, in:title, in:body, and in:comments for fields, repo:, user:, and org: for scope, plus state:, label:, and reason:.
Different patterns suggest different article formats:
| Query pattern | Candidate article type | Example title direction |
|---|---|---|
| bug + in:title + error keyword | Troubleshooting | ”Common errors after an upgrade” |
| enhancement + in:title | Comparison or migration | ”New feature vs old approach: a practical comparison” |
| discussion + in:body + “best practice” | Best practices | ”Practical approaches from a maintainer forum” |
| closed + reason:“completed” | Release analysis | ”What’s new in v2.0: verified issues and migration notes” |
Fallbacks for rate limits and incomplete_results
After each API call, read the x-ratelimit-* response headers first. Call GET /rate_limit when you need a summary across resource buckets. If a limit is exceeded, wait until retry-after or x-ratelimit-reset; if failures continue, use exponential backoff and eventually stop retrying.
When incomplete_results: true appears, mark the candidate card as “data may be incomplete; manual follow-up required” instead of treating the result as exhaustive. Stars and response counts can be supporting signals, but neither should become the only ranking factor.
Reddit input: a read-only allowlist and access risks
Forum posts can supply realistic reader phrasing and pain-point terms, but Reddit’s API policy and anti-abuse controls can change, so retrieval is less dependable. Use those signals only for intent and FAQ candidates; technical claims in the article still need official documentation or reproduced errors.
Read-only endpoint allowlist
BetterLink research allows retrieval and search only, with no write operations:
Allowed read-only endpoints:
listing: retrieve post listingscomments: retrieve comments for a postinfo: retrieve metadata for a post or usersearch: search posts
Forbidden write endpoints:
comment: publish a commentsubmit: publish a postvote: cast a votesaveandhide: save or hide a post
If the agent accesses the Reddit API, encode the read-only allowlist in code so a workflow cannot trigger a write endpoint by accident.
Access risks and fallbacks
Reddit access can fail for three common reasons: authorization failure from an expired or insufficient token, a temporary anti-abuse block after excessive traffic, or a Developer Platform policy change that disables an endpoint.
Use this fallback sequence:
- Attempt the Reddit API request → log the error if it fails
- Fall back to accessible community-question search results
- Extract question phrasing and pain-point terms → create FAQ candidates
- Continue scoring and deduplication without stopping the workflow
Even when Reddit retrieval fails, the agent can still use GSC and GitHub; it only loses part of the language and pain-point signal.
Position the data as question input, not proof
Three candidate-table columns make Reddit’s role explicit:
| Column | Purpose | What Reddit data may contain |
|---|---|---|
source_url | Original source | Allowed |
reader_question | Normalized reader phrasing | Allowed and primary use |
evidence_level | Confidence in evidence | Must not populate fact_claim; record only as reader_signal |
For example, the post “How to fix X error after upgrading to v2?” becomes a candidate card with reader_question: "How do I troubleshoot the error after upgrading to v2?" and evidence_level: "community". The score gives that candidate less evidence weight, and the review interface asks for official documentation or a reproduced case.
This separation avoids unsupported claims such as “many people on Reddit are asking.” Reddit provides search-intent language, not proof of a technical fact.
Extract and classify candidate topics
The agent’s core job is to normalize three input sources—GSC, GitHub, and Reddit—into candidate cards, then send them through scoring, deduplication, and risk filters. The workflow has five steps.
Five-step workflow
Step 1: Google first-party data

- Query the Search Console API for
queriesfrom the past 30–90 days - Identify high-impression, low-click queries, using a sample threshold such as impressions > 100 and CTR < 2%
- Find traffic-earning pages that lack an FAQ section
- Output a GSC candidate table with
query,impressions,CTR, andexisting_page
Step 2: GitHub issue classification
- Search issues in batches by repository or organization with the templates above
- Classify
label:bugas troubleshooting,label:enhancementas comparison, and discussions as best-practice candidates - Extract error terms, version numbers, and feature names from issue titles
- Output a GitHub candidate table with
issue_url,suggested_type, andkeywords
Step 3: Reddit and HN pain-point extraction
- Search selected subreddits or HN and extract recurring reader phrasing
- Normalize patterns such as “How to fix X,” “Why does X happen,” and “Best way to do X”
- Use these posts to phrase questions, not to prove technical facts
- Output a question table with
source_url,reader_question, andevidence_level: community
Step 4: Deduplication and internal search
- Search the site using each candidate’s keywords
- Check whether a GSC query already has a page that covers the intent
- Calculate title similarity so “errors after an upgrade” and “upgrade error handling” do not become separate duplicates
- Output deduplicated cards with
duplicate_check_result
Step 5: Human review
- Before admitting a card, review:
- Whether the scores for search opportunity, site fit, added value, and verifiability make sense
- Whether the title direction and keywords are accurate
- Whether the right action is a new article or an FAQ update to an existing post
- Output approved candidate cards to the content backlog
This is not a fully autonomous workflow. The agent automates collection and produces structured output, but a person makes the final editorial decision.
Score search opportunity, site fit, added value, and verifiability
A topic is not worth publishing merely because it is popular. The agent should score whether the idea fits the site, adds something not already covered, and can be supported with verifiable sources.
Scoring dimensions
| Dimension | Weight | Evaluation signals | Data source |
|---|---|---|---|
| Search opportunity | w1, for example 0.3 | GSC impressions, query volume, competitor coverage | Search Console, third-party SEO tools |
| Site fit | w2, for example 0.25 | Site scope, series membership, tag alignment | Site configuration, series list, tag library |
| Added value | w3, for example 0.25 | Similar internal posts and quality of existing SERP coverage | Internal search, competitor research |
| Verifiability | w4, for example 0.2 | Official docs, issues, releases, and reproducible tests | Source metadata, evidence_level |
Formula: total_score = w1*search_value + w2*site_match + w3*value_added + w4*verify
Score each dimension from 0 to 1, which keeps total_score in the same range. A sample threshold of 0.6 can mark lower-scoring candidates as “hold for review” instead of admitting them automatically.
Example score: “Troubleshoot errors after an upgrade”
Assume the candidate comes from is:issue state:open label:bug in:title error after upgrading to v2. The site focuses on DevOps and containers, and the normalized topic is “Common errors after an upgrade.”
| Dimension | Score | Rationale |
|---|---|---|
| Search opportunity | 0.7 | GSC contains a related query with moderate impressions; competing articles are fragmented |
| Site fit | 0.8 | The site has a container-upgrade series and a DevOps tag; the candidate fills a series gap |
| Added value | 0.6 | An existing “upgrade notes” post lacks troubleshooting; the team could extend it or create a focused child article |
| Verifiability | 0.9 | A GitHub issue and official release note describe the breaking change, and the error can be reproduced |
total_score = 0.3*0.7 + 0.25*0.8 + 0.25*0.6 + 0.2*0.9 = 0.21 + 0.2 + 0.15 + 0.18 = 0.74
Because 0.74 > 0.6, the candidate enters human review. The reviewer also sees a recommendation: update the existing article first, or create a focused child article if the scope warrants one.
This framework prevents two common errors: chasing demand that does not fit the site and publishing duplicate coverage that adds no meaningful evidence or experience.
Apply deduplication, evidence tiers, and risk gates
Before a candidate enters the backlog, it should pass three gates: internal deduplication, source-confidence classification, and a Google quality-risk check. Together they expose duplicates, weak evidence, and scaled-content risks.
Three-gate checklist
Gate 1: Internal deduplication
- Check whether a GSC query already has a dedicated page
- Search the site for similar titles
- Compare title similarity so “upgrade error troubleshooting” and “handling errors after an upgrade” are not treated as separate ideas
- Write
unique,similar_to_existing, orduplicatetoduplicate_check_result
Gate 2: Evidence confidence

- Set
evidence_level:high: official help or docs, an issue with an official response, or first-hand test datamedium: a community post or independent publication without maintainer confirmationlow: unknown source, no link, or unsupported inference
- Require
evidence_levelon every candidate card
Gate 3: Google quality risk
- Check whether the candidate encourages scaled low-value content:
- Is it just the same article with a parameter swapped, such as near-identical Cloudflare Workers and Cloudflare Pages setup posts?
- Does it add a new angle, reproducible test, or operational judgment beyond strong existing coverage?
- Does the fact-checking plan keep Reddit questions separate from official evidence or test results?
- Write
safe,batch_risk,no_value_added, orfact_check_neededtorisk_flag
Evidence-tier reference
| evidence_level | Source type | Example | Follow-up |
|---|---|---|---|
| high | official/help/docs | Google Search Console help, or a GitHub issue with a maintainer response | May support a claim when the source URL is retained |
| medium | community/blog | Forum thread, independent post, or technical blog | Use for reader phrasing; add a primary source for the article |
| low | unknown | No source URL, pure inference, or fabricated data | Reject it or move it to a research-needed queue |
Every candidate card needs evidence_level so reviewers can immediately see which ideas require stronger sources. A GitHub issue with a maintainer response might be high; a user-only discussion remains medium.
These gates assign visible states rather than silently deleting every risky candidate. A flagged card can reach a review queue, but the person sees the problem before deciding what to do.
Store candidate cards and admit them to the backlog
The agent’s final output is a candidate card, not an article. After human approval, the card becomes a content-backlog record for downstream keyword clustering and writing agents.
Candidate-card fields
| Field | Type | Description | Example |
|---|---|---|---|
source_url | string | Original source | https://github.com/user/repo/issues/123 |
reader_question | string | Normalized reader question | ”How do I troubleshoot errors after upgrading to v2?” |
evidence_level | enum | Source confidence | high / medium / low |
search_value_score | number | Search opportunity from 0 to 1 | 0.7 |
site_match_score | number | Site fit from 0 to 1 | 0.8 |
value_score | number | Added value from 0 to 1 | 0.6 |
verify_score | number | Verifiability from 0 to 1 | 0.9 |
total_score | number | Weighted total from 0 to 1 | 0.74 |
suggested_type | enum | Recommended format | troubleshooting / comparison / best_practice / migration / release_update |
suggested_series | string | Recommended series | cloudflare-bindui, when the site has that series |
duplicate_check_result | enum | Internal overlap result | unique / similar_to_existing / duplicate |
risk_flag | enum | Quality-risk flag | safe / batch_risk / no_value_added / fact_check_needed |
Candidate cards can be stored as JSON or database records. Reviewers see all fields instead of making a decision from a title and popularity metric alone.
Backlog fields
An approved candidate becomes a backlog record with:
- Title, finalized during human review
- Primary and secondary keywords
- Status:
to_write,writing,review, orpublished - The candidate’s
total_score - Locale, such as zh or en, based on site configuration
- Series, when
suggested_seriesis valid - Planned publication date and priority
The next article can define the complete backlog schema and API. This workflow covers only how a candidate card earns admission.
Human review workflow
Before admission, a person checks:
- Score review: Does
total_scoremake sense, and does a low dimension such asverify_score = 0.2require more evidence? - Title and keyword review: Does
reader_questioncapture the problem accurately, and should the keywords change? - Second internal-search check: Did the automated deduplication miss a similar article?
- Admission decision: Approve, reject, or request more evidence, with the reason recorded
The flow is agent extraction → structured scoring and filtering → human review → admission. Automation organizes scattered signals into comparable cards, while editorial responsibility stays with a person.
Next steps and related reading
After scoring and review, the usual next stages are keyword clustering, backlog management, and writing planning. These articles provide useful implementation context:
- AI research agent: from multi-platform search to an evidence report
- Weekly GA/GSC operations SOP for high-impression, low-click pages
- Advanced Google Search Console techniques
- Quarterly topic planning for technical blogs
A topic research agent is only the first stage of content-site automation. It turns signals from several sources into reviewable candidates; clustering, task management, writing verification, and content refreshes remain separate downstream responsibilities.
Build a minimum viable AI topic research agent
Normalize signals from several sources into candidate cards, score and deduplicate them, and write only human-approved items to the content backlog.
- 1
Step 1: Load the content inventory
Read existing posts, series plans, and tags to establish a baseline for deduplication and site-fit scoring. - 2
Step 2: Pull GSC data
Retrieve clicks, impressions, CTR, and average position by query and page, then flag existing demand and coverage gaps. - 3
Step 3: Add external context
Use general search for SERP questions and primary sources, and save the query, timestamp, URL, and retrieval status. - 4
Step 4: Collect community and issue signals read-only
Extract question phrasing from Reddit and error, version, or feature friction from GitHub issues without performing write operations. - 5
Step 5: Normalize and score candidates
Create candidate cards and score search opportunity, site fit, added value, and verifiability. - 6
Step 6: Deduplicate and filter risks
Normalize entities and intent, then check internal overlap, evidence tiers, scaled-content risk, and volatile facts. - 7
Step 7: Review and admit candidates
Have a person review the highest-ranked cards, write only approved items to the backlog, and record whether to create, refresh, extend, merge, or discard.
FAQ
Should a topic research agent scrape Google results or use Search Console data?
Can a popular Reddit post become a blog topic directly?
What technical topics can GitHub issues reveal?
How can you distinguish real demand from a one-off complaint?
Should the workflow stop when GitHub Search or Reddit access fails?
Is Google Custom Search JSON API suitable for a new project?
What should a person review before a candidate enters the content backlog?
13 min read · Published on: Nov 13, 2026

AI Content Site Automation Guides: Planning, Writing, Publishing, and Ops
If you landed here from search, the fastest way to build context is to jump to the previous or next post in this same series.
Previous
Can AI Content Still Rank? Google's Rules for Scale and Quality
Google's guidance explains when AI-assisted publishing is acceptable, when scaled content becomes spam, and which human review checks reduce risk.
Part 1 of 4
Next
AI Keyword Clustering: Turn Search Queries into Content Series and Internal Links
Combine GSC queries, topic ideas, and existing posts, then use semantic grouping, SERP checks, and human review to map clusters to pages, updates, FAQs, and links.
Part 3 of 4


Comments
Sign in with GitHub to leave a comment